
大家好,又见面了,我是你们的朋友全栈君。
文章目录
前言
在一级项目组时,监控服务器的同时,总结了一下SQL关于查询的语句,希望能给大家带来一些帮助
推荐两个博客,下面借鉴了这两个
菜鸟教程
网上大佬的
之前的总结
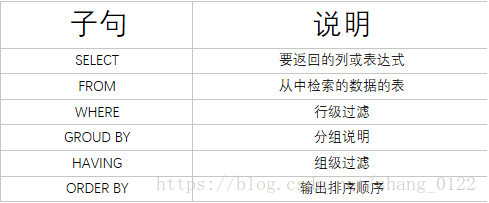

这次在之前的基础上扩展一些内容,分别在字句的后面扩展更多的表达式或者函数。
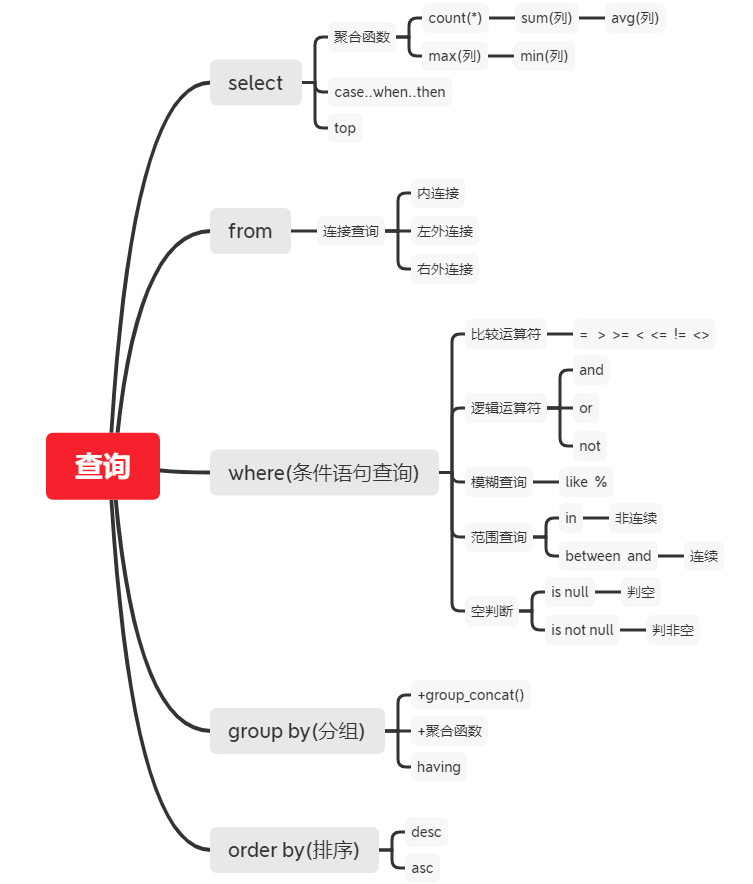
下面会用到一级中具体某个表,会有说明
Select
Select+聚合函数
总数
count(*)表示计算总行数,括号中写星与列名,结果相同
例1.查询登录系统学总数
select count(*) from StudentBindPaperTypeEntity
最大值
max(列)求此列的最大值
例2.求下表的最大编号
select max(StudentID) from StudentBindPaperTypeEntity
最小值
min(列)求此列的最小值
例3.求下表编号最小编号
select min(StudentID) from StudentBindPaperTypeEntity
求和
sum(列)求此列之和(注:sum运算符与数字类型连用)
例4.查询当前在线的学生(IsUse=0表示未在线,1表示在线)
select SUM(IsUse) from StudentBindPaperTypeEntity
平均值
avg(列) 表示求此列的平均值(注:avg运算符与数字类型连用)
例5:查询学生编号的平均数
select avg(StudentID) from StudentBindPaperTypeEntity
Select+case…when…then语句
case…when…then语句,相当于编程语言中if判断
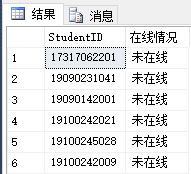
例1根据IsUser字段查询学生是否在线
select a.StudentID,
	(case a.IsUse
	when '0' then '未在线'
	when '1' then '在线' else '未上传' end) as 在线情况
from StudentBindPaperTypeEntity as a
显示情况:
select+top
top:取表中前多少的数据
例1.取出表中第几行数据(如第一行)
select top 1 * from StudentBindPaperTypeEntity
例2.取出表中百分之多少数据
select top 50 percent * from StudentBindPaperTypeEntity
from(表)+连接查询
连接查询
- 内连接:Inner join
- 左连接:Left join
- 右连接:Right join
例子中涉及的表
- StudentInfoEntity:全校学生的信息
- ScoreEntity:学生考试的成绩(并不全包含全校学生)
from+inner join
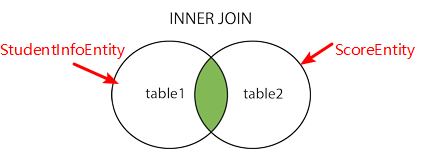
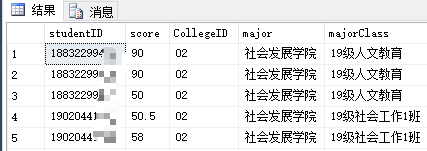
例1.查出这两个表中共有的信息(as为表的别名,方便)
select score.studentID,score.score,s.CollegeID,s.major,s.majorClass
from ScoreEntity as score inner join StudentInfoEntity as s on score.studentID=s.studentID
where score.CollegeID=02
显示结果
from+left join
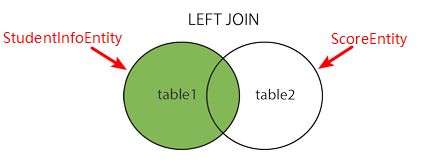
左外连接:左表的值会全部显示出来,右表的值显示on条件搜索的的结果,搜索不到为NULL
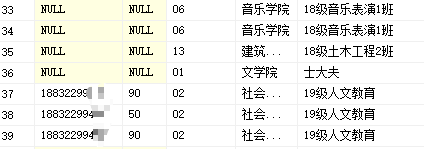
例1两个表作左外连接
select score.studentID,score.score,s.CollegeID,s.major,s.majorClass
from  StudentInfoEntity as s left join ScoreEntity as score on s.studentID=score.studentID
显示结果:(个别)
from+right join
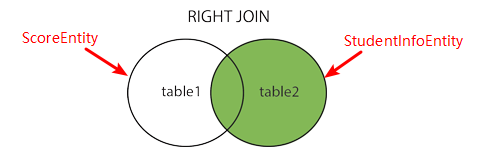
右外连接与左外连接相反(右表的值全部显示出来)
例1两个表做右外连接
select score.studentID,score.score,s.CollegeID,s.major,s.majorClass
from  ScoreEntity as score  right join StudentInfoEntity as s on s.studentID=score.studentID
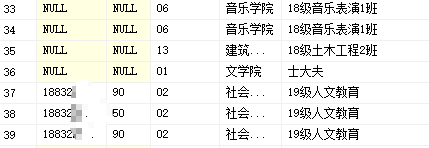
现在两个表换了位置,结果是一样的
Where(条件语句查询)
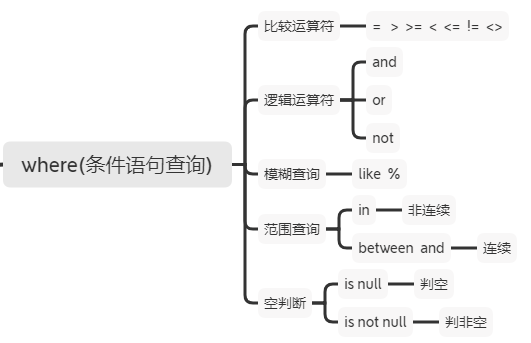
比较运算符
例1.查询学号>18832650890的学生
select * from StudentBindPaperTypeEntity where StudentID>18832650890
例2.查询学号!=18832650890的学生(<>同效)
select * from StudentBindPaperTypeEntity where StudentID!=18832650890
模糊查询
like
%表示任意多个字符
例1.查询1月8号考试的学生
select * from StudentBindPaperTypeEntity where TimeTamp like '2020-01-08%'
例2.查询不是1月8号考试的学生
select * from StudentBindPaperTypeEntity where TimeTamp not like '2020-01-08%'
范围查询
in关键字为非连续查询
例1.查询两个不相邻的学号的学生
select * from StudentBindPaperTypeEntity where StudentID in('19100142001','19100142006')
Between…and…为连续查询(注:sql软件情况不一样,可能不包含and后的值)
例2.查询两个学号之间的学生
select * from StudentBindPaperTypeEntity where StudentID Between 19100142001 and 19100142006
空判断
is null判断为空
例1.查询没有试卷的学生
select * from StudentBindPaperTypeEntity where PaperType is null
is not null 判断非空
例2.查询有试卷的学生
select * from StudentBindPaperTypeEntity where PaperType is not null
优先级
优先级由高到低的顺序为:小括号,not,比较运算符,逻辑运算符
and比or先运算,如果同时出现并希望先算or,需要结合()使用
group by(分组)
作用:将字段间一对多的关系,向一的方向靠拢分组
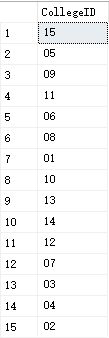
例1.查出参加考试有几个学院
select CollegeID from StudentBindPaperTypeEntity group by CollegeID
显示结果:
group by+聚合函数
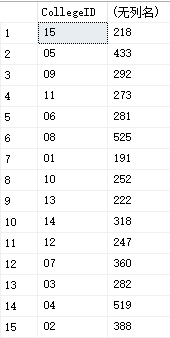
例2.查出各个学院参加考试的人数
select CollegeID, count(StudentID) from StudentBindPaperTypeEntity group by CollegeID
显示结果:
其实group by + 聚合函数是从group by + group_concat()演变过来的,SqlServer不支持这个函数
group by+having
having的作用跟where子句功能一样,只不过having只用在group by
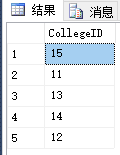
例3.查出学院ID大于10的学院
select CollegeID from StudentBindPaperTypeEntity group by CollegeID having CollegeID>10
显示结果:
Order by(排序)
排序查询语法:
select * from 表名 order by 列1 asc|desc [,列2 asc|desc,...]
- 如果列1的值相同,则按照列2排序,以此类推
- asc从小到大
- desc从大到小
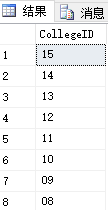
例1.根据学院分组ID降序(desc)
select CollegeID from StudentBindPaperTypeEntity group by CollegeID order by CollegeID desc
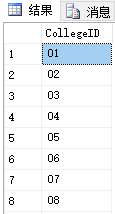
例2.将上表升序(asc)
select CollegeID from StudentBindPaperTypeEntity group by CollegeID order by CollegeID asc
发布者:全栈程序员-站长,转载请注明出处:https://javaforall.net/131539.html原文链接:https://javaforall.net


